
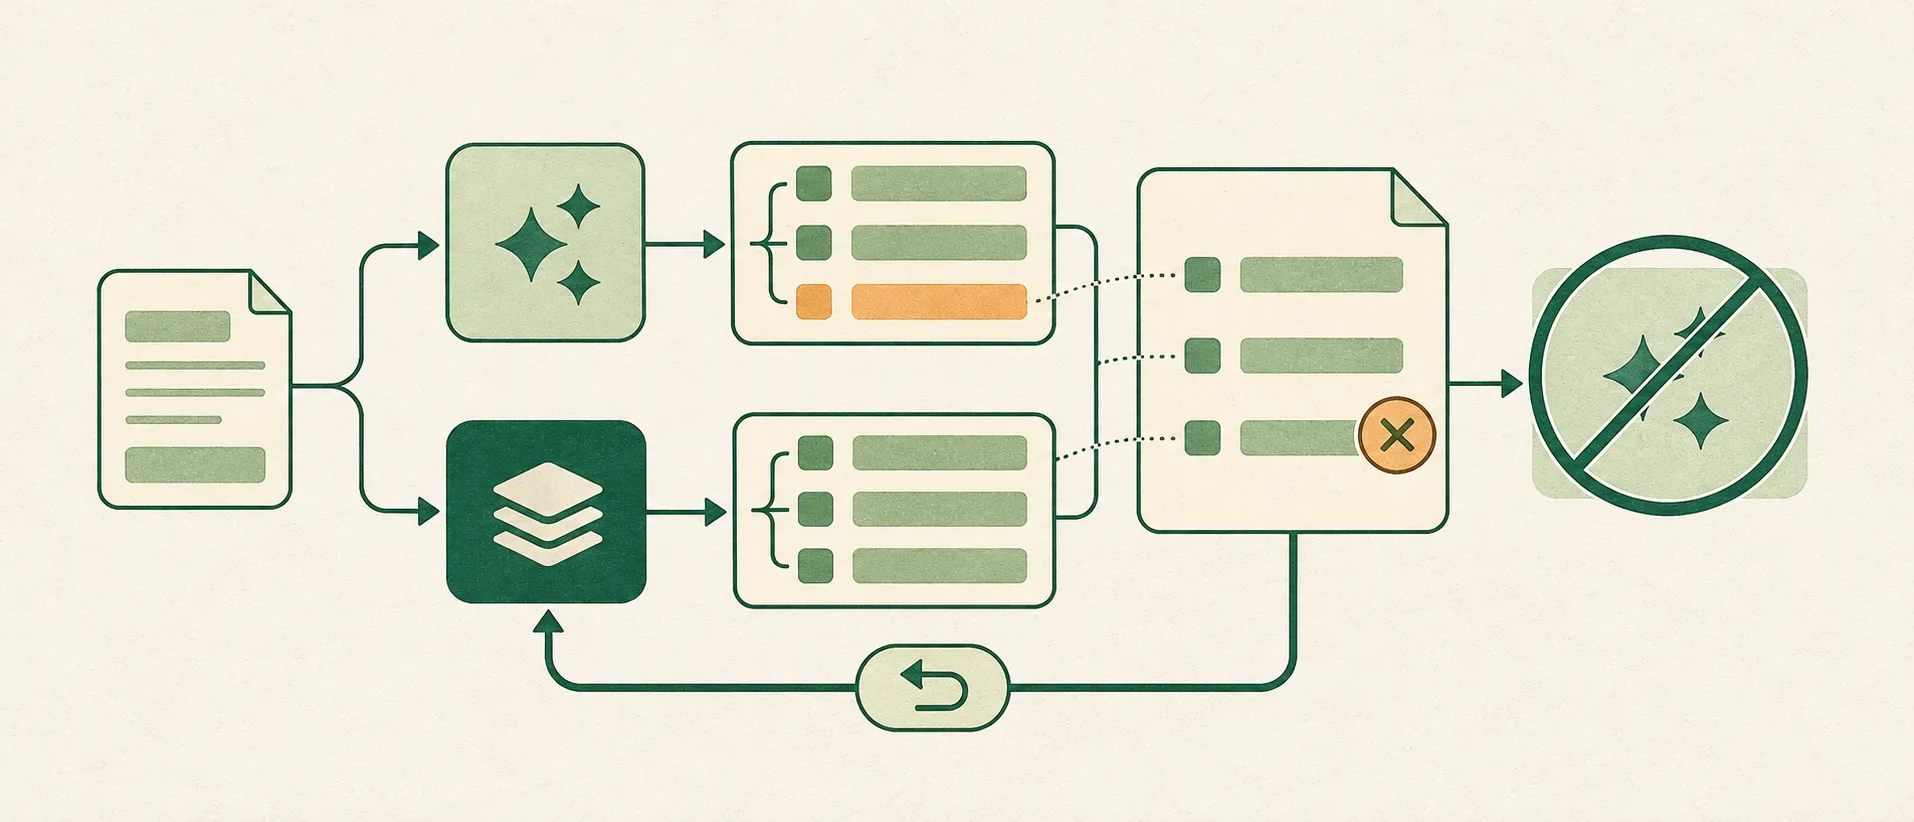
Upgrading An LLM Version Requires Data Migration Thinking
By wGrow Project Team ·
If a team moves its lead-qualification bot from Claude 3 Sonnet to Claude 3.5 Sonnet, and the provider calls it an upgrade, the team may treat it like a patch release — bump the model string, redeploy, move on with the day. A few days later, a share of inbound leads can quietly vanish, and the only way to see it is by comparing web-form submissions against successful CRM writes.
Nothing crashes. There are no error logs, no 500s, no alerts firing. The bot keeps answering. The CRM pipeline keeps humming along as if everything is fine. That’s what makes it dangerous — a silent failure doesn’t page anyone. It just costs you money until someone in sales finally asks why the pipeline looks thin.
Silent Regressions in JSON Output
A bot’s job is simple: parse an inbound message, extract lead attributes, emit a flat JSON object, hand it to a Python function that writes to the CRM. The older model may have reliably produced {"name": ..., "company": ..., "intent": ..., "budget_band": ...} for months, and the parser can end up written against that exact shape, and only that shape.
A newer model can produce something structurally different, and any difference the parser doesn’t expect matters. It might nest budget_band inside a qualification object. It might occasionally add a confidence key nobody asked for. Sometimes it might wrap the whole thing in a lead envelope, because the new model’s training has given it a different instinct for what “helpful” formatting looks like. None of this is wrong, exactly. It just isn’t what the parser expects — and that gap is where the damage happens.
Python code does what brittle glue code does when an expected field moves behind an extra layer of nesting: it throws a KeyError reaching for budget_band where a flat top-level key used to be. If that exception is swallowed by a broad try/except further up the stack — the team’s mistake, not the model’s — the lead silently drops instead of writing to the CRM. Matching inbound submissions against CRM write records would reveal the gap, but there is zero signal until someone compares pipeline volume against CRM entries.
The lesson: a model upgrade inside a multi-agent system is not a library dependency bump. It’s a breaking structural change to a contract you didn’t know you had.
The Architecture of Schema Drift
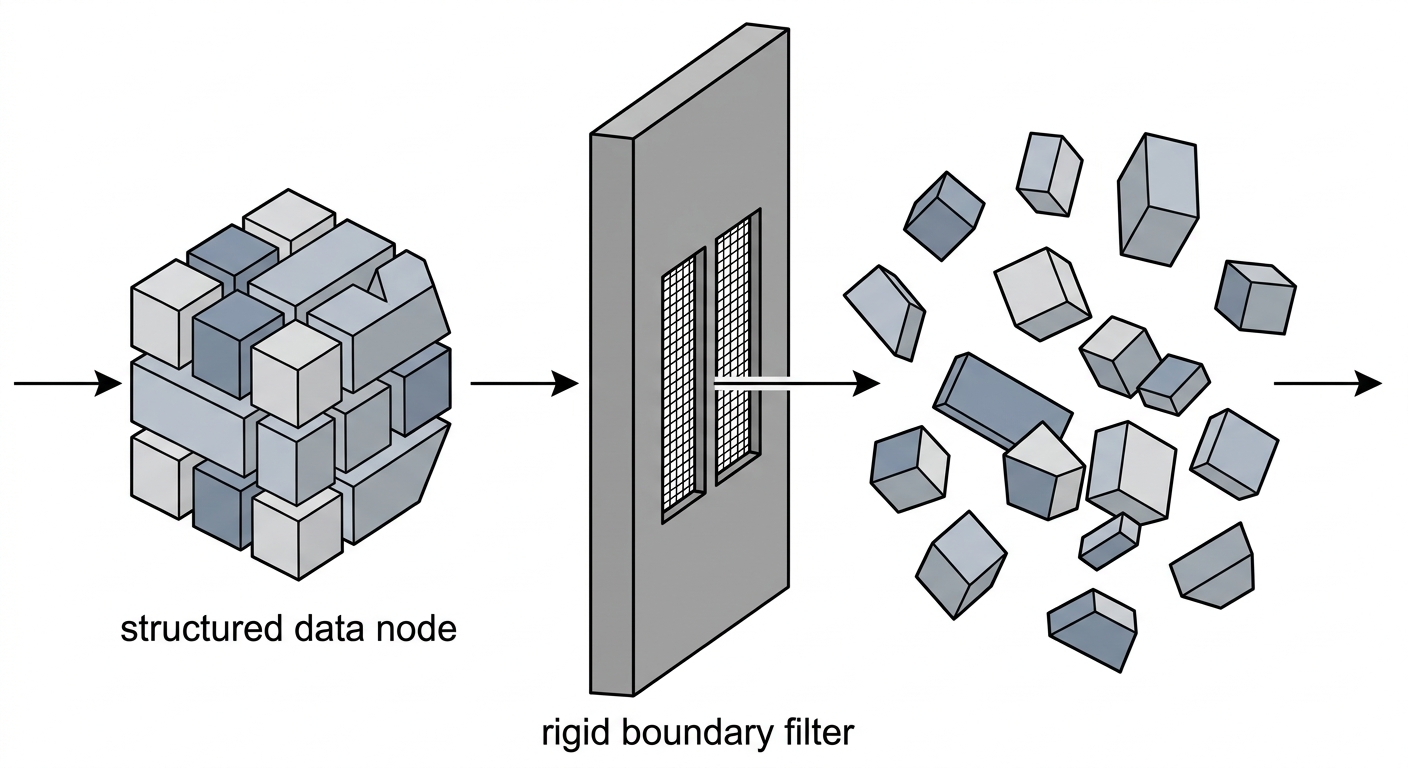
| 1 | { | |
| 2 | "lead": { | ← ① |
| 3 | "name": "John Doe", | |
| 4 | "metadata": { | ← ② |
| 5 | "score": 85 | |
| 6 | } | |
| 7 | } | |
| 8 | } |
- ① Unexpected nesting (previously flat)
- ② Hallucinated 'metadata' key
Multi-agent systems run on contracts. Agent A emits a JSON object. Agent B parses it and calls a tool. Agent C reads the tool’s output and decides what happens next. That’s the same basic shape as a service boundary in any distributed system — except the thing generating the payload on one side is a probabilistic model, not a compiler.
LLMs don’t owe you backwards compatibility on output formatting. There’s no semver contract that says “3.5 will format JSON the way 3.0 did.” When a provider fine-tunes a new version, it changes the token probability distribution end to end — which reshapes formatting habits, reasoning paths, and which edge cases get handled inline versus flagged separately. None of that shows up in the model card. Any of it can show up in your parser, eventually, at the worst time.
Teams that build multi-agent crews around rigid prompt engineering — “the model will always return exactly this shape because I told it to in the system prompt” — are building on a foundation that can shift under them with any new checkpoint. The better mental model isn’t “I called a function and got a return value.” It’s “I ran a query against a table, and the table’s schema can change without my permission, on someone else’s release schedule.”
Treat it that way, and the rest of the operational discipline follows on its own.
Shadow Traffic and Parallel Staging
A second, higher-stakes version of this problem can appear for a team running a sensor anomaly detection system for water quality monitoring, where the output isn’t a CRM record but an alert to a facility manager who may or may not shut down a pump based on what the model just told them.
When that team needs to move the classification layer from GPT-4-Turbo to GPT-4o, hot-swapping the model string in production is simply off the table, as the lead-bot scenario above shows. Instead, build a parallel staging path: route every real sensor reading from production to both models simultaneously, for a meaningful stretch of time, before GPT-4o is allowed anywhere near a customer.
Diff the two models’ classification boundaries regularly. They won’t agree on everything. A newer model might group certain water quality anomalies differently — some borderline readings that the older model classified as noise, the newer one might flag as early-stage anomalies worth a second look. That’s not necessarily wrong. It might even be an improvement. But “might be an improvement” isn’t something you want to discover for the first time in production, on a system where a false negative means a water-quality anomaly goes unflagged and a false positive means a facility manager starts tuning out alerts from fatigue.
Shadow traffic against real sensor data gives the actual delta between models on your specific distribution of edge cases — not on whatever benchmark the provider used to announce the upgrade. Synthetic test suites are good at catching regressions you already anticipated. They’re close to useless against reasoning drift you didn’t anticipate, because you can’t write a test for a failure mode you don’t know exists yet. I’d rely on real production data run in parallel to surface that kind of drift before it costs you something.
The Operational Playbook for Model Migrations
A few rules follow from both scenarios. Run them as a checklist before any model swap, no exceptions:
Lock model versions in production code. Never deploy against a floating alias like gpt-4 or claude-3-sonnet. Pin the dated release string — a floating alias means the provider can change your production behavior on their schedule, not yours.
Treat models as immutable dependencies in your eval pipeline. Change the model, run the full regression suite — the same one you’d run for a database engine version bump. “It’s just a text model” isn’t an exemption.
Write defensive parsers on every agent-to-agent boundary. Missing keys, unexpected nesting, extra fields — all of it should degrade gracefully, not throw and get silently caught three layers up. A payload that doesn’t match the expected schema should trigger a loud, logged, alertable event. Not a quiet drop.
Instrument the parsing layer, not just the API layer. If observability only watches for HTTP errors and latency spikes, it won’t catch “the JSON parsed fine but the values are semantically wrong” — which is exactly the failure mode in the lead-bot scenario. Log agent payload failures, including the ones that parsed successfully but drifted from the expected schema, to a central dashboard. Alert on volume anomalies the same way you’d alert on a sudden drop in database write throughput.
The Deprecation Window Reality
Here’s the part that doesn’t go away once the parsers are fixed: providers deprecate models on their own timeline, not yours. When an API provider announces deprecation, the published shutdown date is a hard migration deadline, not an opening offer — the exact window varies by provider and by model family, but the operational problem is the same either way: the moment the notice goes out, you’re on a countdown.
Treat that window the way you’d treat a PostgreSQL major-version migration — budget an actual engineering sprint for it, not a Friday afternoon. Rewrite prompts against the new model’s formatting habits, re-run the regression suite, and stand up shadow traffic if the system is high-stakes enough to warrant it. And if it touches a customer’s water supply or their CRM revenue, it is.
Agentic systems built on rented model weights don’t get to be set-and-forget. The intelligence is rented, and the lease terms change without notice. Budgeting for that churn — as a recurring line item, not a one-off firefight — is what separates a multi-agent system that survives its third model upgrade from one that quietly drops something important on the way there.