
Tool-Written Programs Need Fixture Tests
By wGrow Project Team ·
A hardware sensor can return the string 'NULL' instead of an actual null. Small distinction, big consequence: an agentic pipeline built to filter that telemetry evaluates the string as truthy, because in JavaScript any non-empty string is truthy no matter what it says. If the filtering script the model wrote relies on that check, the bad reading sails straight through. Nobody notices until a downstream dashboard shows a chlorine residual number that makes no physical sense.
That’s the failure mode this piece is about. Not the model reasoning badly — the model writing code that nobody checked before it touched live data.
The Invisible Code Path
Some model APIs now support programmatic tool execution, where a model can generate JavaScript to filter, transform, or orchestrate tool outputs instead of processing the whole payload inside the prompt. That’s a genuine efficiency win. You stop paying for the model to eyeball a large sensor payload and instead let it write a short filter that runs once, deterministically, outside the prompt.
The catch is what “outside the prompt” actually means once you look closely. That JavaScript is generated fresh per run, executes with real permissions against real data, and then vanishes. It never gets a code review. It never gets a unit test. It never shows up in a pull request. It behaves like production code, minus every mechanism your team normally relies on to catch production code doing the wrong thing.
Treat model-written glue code as a first-class function in the system — because that’s exactly what it is. If a junior engineer submitted a null-check with no test attached, it wouldn’t get merged. A model shouldn’t get a pass just because it writes the same bug faster.
Silent Failures in Sensor Telemetry

| 1 | function filterTelemetry(payload) { | |
| 2 | // Generated by model to remove nulls | |
| 3 | return payload.filter(r => r.value); | ← ① |
| 4 | } | |
| 5 |
- ① Evaluates string 'NULL' as truthy, passing bad data
Picture an ingest pipeline that uses an agentic step to parse anomalous readings before they hit downstream analytics. To save tokens, the model generates a small JavaScript filter that strips null values out of the payload before further processing — sensible design, on paper. The hardware API may return 'NULL' as a string on certain firmware versions, not a native null. Boolean('NULL') evaluates to true. The generated filter never flags it, the record sails through, and the pipeline ingests a garbage value as if it were legitimate telemetry.
Nothing crashes. That’s the part worth sitting with. A crash is diagnosable — you get a stack trace, a timestamp, a starting point. A silent pass-through of bad data into a downstream dashboard isn’t diagnosable at all, not until someone notices the numbers look wrong. A single fixture test, one mocked payload with 'NULL' as a string, would catch this before the script ever touches production data.
Breaking on Currency Formats
The same class of bug can turn up in a completely unrelated system: an HR claims agent uses programmatic tool calling to generate regex that extracts receipt totals from raw OCR text. The model-written extraction logic might handle SGD and USD formats cleanly, then break entirely on Malaysian Ringgit receipts, because RM formatting in the OCR output carries unexpected whitespace the generated regex never accounted for.
Same root cause as the telemetry bug, different domain entirely: the model writes code that looks correct against the inputs it implicitly assumed, and those assumptions don’t hold for every real payload. Two unrelated systems with no shared codebase between them could still show the same failure shape. That’s not coincidence. That’s what happens by default when generated code ships without a test suite behind it.
The fix isn’t a smarter prompt. It’s a set of golden malformed payloads — RM receipts with the exact whitespace quirks that break a naive first version — run against every newly generated extraction script before it’s allowed anywhere near live claims.
Building the Verification Harness

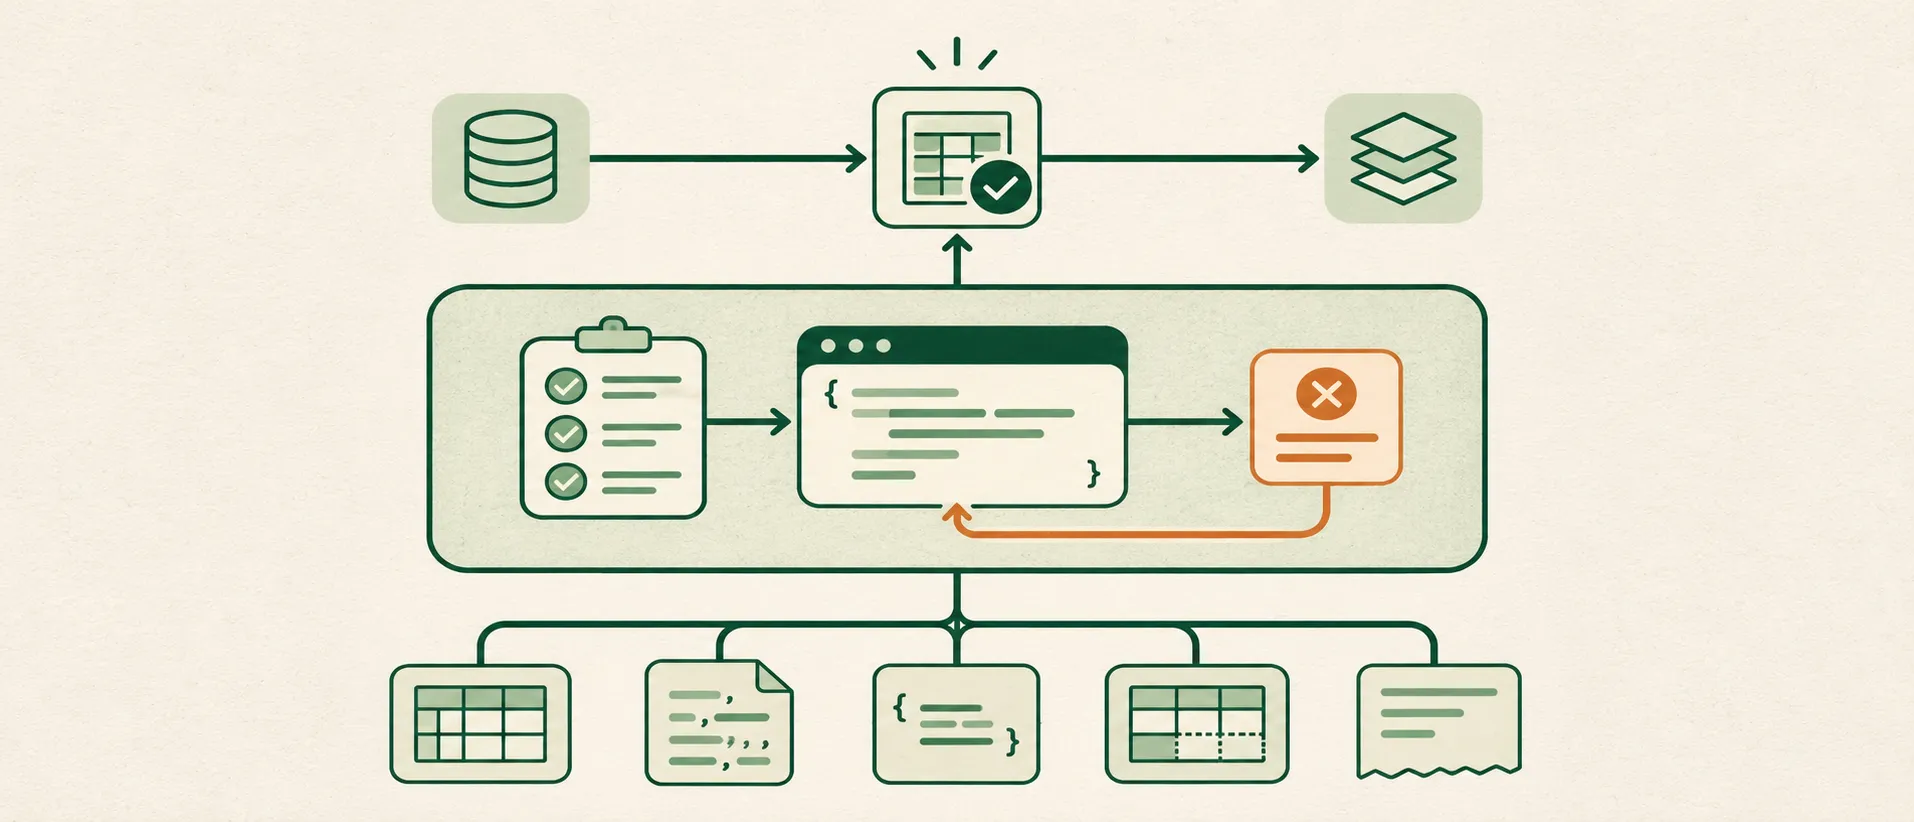
The operational answer is boring, and boring is correct here. Treat every prompt that generates temporary code as a function signature requiring tests, full stop, regardless of who or what wrote the body.
In practice, that means maintaining a fixture pack per tool-output shape: the null-as-string, the malformed currency string, the empty array, the unexpected key. Run each newly generated script against that pack before it earns execution permission on real data. Do this in CI, not as a one-off review step — the entire premise of programmatic tool calling is that the code gets regenerated on every run, so a review you did last week tells you nothing about the script running today.
This isn’t a complete guarantee, and it’s worth saying plainly. A fixture pack only catches the failure shapes you’ve already thought to encode. A new firmware version, a new currency, a new OCR quirk — any of those can still slip through on day one. The value here isn’t eliminating that risk. It’s shrinking the set of known failure modes that ever reach production, and folding every new one you find back into the pack instead of letting it stay a one-off war story.
And define, explicitly, what failure should look like. A generated filter that hits a shape it doesn’t recognize should throw — loudly, and stop the pipeline cold. It should not quietly pass the bad value through just to keep the agent loop moving. A pipeline that swallows the error to keep things running can let a 'NULL' string become a chlorine reading on a downstream dashboard.
Token Savings Do Not Waive Test Obligations
Human-written microservices need test coverage as a baseline, not a courtesy. There’s no defensible reason to accept zero coverage for model-written runtime scripts just because the model produces them faster and cheaper than a person would by hand.
Building and maintaining fixture packs isn’t free, either — it’s real engineering time you didn’t have to spend when the code was just running unchecked. Weigh that cost against the token savings programmatic tool calling delivers. But for pipelines touching live data, the math favors building the harness: one bad chlorine reading in front of a client costs a lot more than the fixture pack that would have stopped it.
If you’re running agentic workflows against production data today, you own whatever code the model writes — the same way you’d own a contractor’s commit. Token efficiency is a real win. It is not an exemption from basic software engineering discipline. Build the fixture packs before the model finds your edge cases for you, in production, with a customer watching the dashboard.