
The 'Model Did It' Is Not An Incident Report
By wGrow Project Team ·
Blaming the model is an incident-response failure. When an agent misfires in production — wrong output, wrong API call, wrong data written to the wrong record — the first question in the post-mortem should not be “what did the LLM do?” It should be “who owns the agent?”
Without a clean answer to that second question, the agent runs. Something breaks. The incident ticket says “model behaviour was non-deterministic.” That sentence is not a finding. It is an admission that the system was ungoverned.
Treat an unowned agent in production the same way you would treat an unauthenticated API endpoint: as a critical vulnerability. Not a product risk. Not a people problem. A compliance gap that cannot close itself.
The fix is structural. Every deployment manifest must carry an owner tag. Not a team, not a role. A named person. If the agent breaks something, that person writes the incident report.
CI/CD Governance and the Owner Annotation
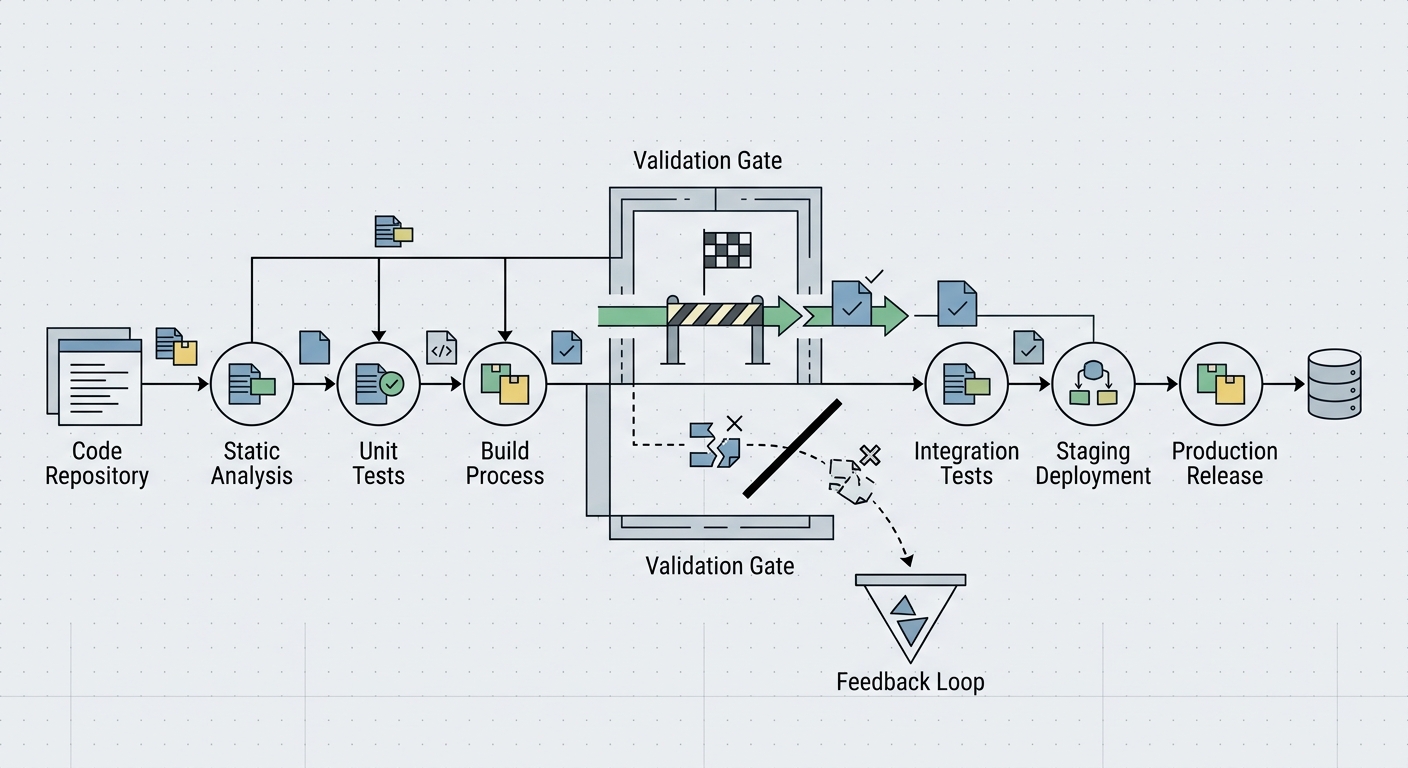
The enforcement mechanism lives in the pipeline. A continuous integration pipeline should validate every Kubernetes manifest before it reaches the production cluster. If the manifest is missing the x-agent-owner annotation, the pull request should be blocked. Not flagged, not warned. Blocked.
apiVersion: apps/v1
kind: Deployment
metadata:
  name: hr-screener-agent
  annotations:
    x-agent-owner: "E00247"
    x-agent-tier: "production"
    x-agent-review-date: "2026-09-30"
spec:
  replicas: 2
E00247 is an employee ID. It resolves to a name, a manager, and a calendar. When the HR screening agent misfires on a candidate record, there is no ambiguity about who initiates the review.
Apply the policy with no carve-outs — not for “experimental” agents, not for “low-stakes” workflows. Experimental agents belong in staging environments, not production clusters. “Low-stakes” is a risk assessment that belongs on paper before deployment, not a justification for skipping governance after the fact. The annotation is binary: present means deployable, absent means the pipeline stops.
One objection is that this slows velocity. It does not. The annotation is a small manifest change. Reconstructing agent ownership after a data incident, under audit conditions, is the slow path.
Incident Routing in a Diagnostic Pipeline
| 1 | apiVersion: apps/v1 | |
| 2 | kind: Deployment | |
| 3 | metadata: | |
| 4 | name: hr-policy-agent | |
| 5 | annotations: | |
| 6 | x-agent-owner: "emp_4092" | ← ① |
| 7 |
- ① PR is blocked if this is missing
The tagging isn’t just a deployment gate. It is what routes the first call when something breaks.
A diagnostic pipeline runs sensor parsing models against water quality telemetry. The models classify anomalies, flag contamination signals, and trigger downstream alerts. On a potable water system, a false diagnostic is not a user-experience failure. The consequences are operational and safety-critical.
Every sensor parsing model in such a pipeline should be tagged to a designated data engineer via the manifest. When a model exceeds its latency budget, returns a classification outside the expected distribution, or generates a diagnostic that fails the downstream sanity check, telemetry should read the manifest tag and page the engineer directly — not a triage queue, not an on-call rotation of people who did not build the model.
The incentive effect is intentional. Engineers who know they will be paged for a hallucinated diagnostic have a direct reason to build better upstream guardrails: stricter parsing schemas, tighter input validation on the sensor payload. Accountability shifts the engineering calculus in ways that code review alone does not — though it works best when post-mortems focus on systemic failure rather than individual blame.
The post-mortem format for an agent incident should follow the same structure as any other service failure: timeline, blast radius, contributing factors, corrective actions. “The model was non-deterministic” is not a valid entry in the contributing factors field. It describes the technology. The post-mortem requires an explanation of why the system had no safeguard against that non-determinism. The tagged owner answers that question.
Mandate Ownership Before the Auditors Do
Update your deployment pipelines to reject untagged agents now. Not after the next incident. Not after the compliance review.
Legal and regulatory accountability for AI behaviour is tightening. The EU AI Act puts obligations on providers and deployers of high-risk AI systems. For regulated Singapore financial institutions, MAS Technology Risk Management guidelines require clear accountability for technology risk management. Neither gives you cover for an unowned production system.
A matrix of weights and biases cannot sign a corrective action plan. It cannot appear before a board. In any compliance audit or post-incident review, “the LLM behaved unexpectedly” is an admission of three failures at once: no owner, no guardrail, and no governance. The organisation assumed the model would be accountable for its own outputs.
Human ownership is the accountability boundary that holds across both regulatory and operational scrutiny. Tag the manifest. Name the engineer. Close the gap before someone else names it for you.