
Agent Framework Choice Is Now A Delivery Risk
By wGrow Project Team ·
pip install langchain runs in seconds. The architectural debt it creates takes considerably longer to untangle.
The Illusion of the Free Sandbox
The agent SDK market has no clear winner. LangChain, LlamaIndex, CrewAI, AutoGen, Semantic Kernel, Anthropic’s Claude Agent SDK, and Google’s Agent Development Kit are all actively maintained and competing for the same workloads. Seven frameworks without a dominant pattern isn’t a sign of healthy ecosystem maturity. It’s a sign the market hasn’t yet converged on what agent frameworks are actually for.
That fragmentation sets a specific trap. A developer installs a framework on a Friday to test a prompt chain. The experiment works. The prototype gets demoed. By the following sprint, the prototype has become the foundation — and nobody reviewed the SDK against your actual deployment constraints, nobody asked whether it handles the retry logic your production environment needs, nobody checked whether it can surface the trace data your compliance team will eventually demand.
Selecting an agent framework is an architectural decision with real delivery consequences. It shapes your deployment pipeline, your retry and error-handling model, how state persists across agent handovers, and what it costs to swap the framework out when requirements outgrow the original choice. Treating it like a sandbox exercise doesn’t eliminate those consequences. It just defers them to the worst possible moment.
When a Framework Rewrite Lands Mid-Delivery
A multi-agent procurement system shows how that deferral plays out. The brief: automate vendor sourcing, quote comparison, and approval routing across a procurement team.
Suppose the team starts with LangChain. The documentation is solid, the community large, and the local testing environment behaves exactly as expected.
Scale can break it.
LangChain’s abstraction layer handles simple sequential chains without complaint. Branching, parallel execution, and shared-state requirements across a real procurement crew are a different matter. Agents can lose context between handovers. The framework’s internal state model can conflict with your persistence layer. Debugging can mean working through abstraction layers designed to hide exactly the things you need to see. LangChain has invested significantly in LangSmith for observability, but whether those hooks meet your operational requirements is something to verify, not assume.
Porting the entire system to another framework, say CrewAI, would then consume unplanned engineering time. Small in isolation, significant as unplanned cost on a fixed-scope delivery. It can delay go-live and force scope renegotiation on other workstreams.
The lesson isn’t that LangChain is a poor framework. It’s that the abstraction model of the SDK you choose directly shapes your future delivery cost as requirements scale. A framework optimized for rapid prototyping may actively resist the operational requirements of a production multi-agent system. If you haven’t evaluated that mismatch before you commit, you’ll evaluate it under deadline pressure.
Compliance Black Boxes
A different failure mode is rooted not in state management but in observability.
A diagnostic agent that maps sensor readings against historical patterns to flag anomalies works in a domain where a correct output isn’t sufficient. You need to prove what context was passed to the model and what the raw model response was before any post-processing. For a quality process there, “the output was right” is not a sufficient answer — the diagnostic path must be reconstructable, which means retaining the prompt context, the raw model response, and every post-processing step in a form that could be reviewed later.
An SDK that prioritizes developer ergonomics wraps LLM calls cleanly, reduces boilerplate, and makes the happy path fast to write.
It may also swallow the raw trace data.
If the framework exposes no hooks for extracting pre- and post-inference payloads in the format an audit harness needs, and logs only a processed summary — useful for debugging, insufficient for compliance — the team is left building a custom evaluation harness from scratch to instrument the SDK at a lower level. That work is unbudgeted and introduces a maintenance surface outside the SDK’s upgrade path.
A framework that prioritizes developer convenience over observability will struggle in regulated contexts. This isn’t a configuration problem you can work around. It’s an architectural mismatch — and the only reliable way to catch it early is to require proof of raw trace export capability before you adopt the SDK, not after the first audit request lands.
Mandating the Architecture Decision Record
Both scenarios point to the same failure: a framework choice made without a forcing function for rigor. The fix is procedural.
If a framework choice shapes your testability, your build cost, and your failure modes — and agent SDKs shape all three — it belongs in an Architecture Decision Record. Not a Slack thread. Not a README footnote. A formal ADR with selection criteria, evaluated alternatives, and documented trade-offs.
The required criteria aren’t complicated, but they should be treated as non-negotiable gates, not nice-to-haves.
Observability hooks must be demonstrated, not assumed. The framework must expose raw request and response payloads before post-processing. If you can’t write a test that asserts what the model was actually sent, you can’t produce a compliance audit.
Native support for custom evaluation harnesses is required. You need to inject your own evaluation logic at the agent boundary without forking the framework. If the only path to custom evals is patching internals, that’s a long-term maintenance liability.
Raw trace export must be native, not bolted on. The framework should emit structured traces that integrate with standard observability tooling without bespoke plumbing.
Exit criteria must be defined before adoption. What would force you to replace this framework? State it explicitly in the ADR. If you can’t answer that question before you adopt the SDK, you’re not ready to adopt it.
Strip GitHub stars, social media reach, and demo-to-production speed from your evaluation criteria entirely. Those metrics measure visibility. They say nothing about operational fitness.
Plan for Framework Obsolescence
Assume the framework you choose today may become a legacy dependency within the life of your product roadmap. The same fragmentation that makes selection hard also makes any individual choice vulnerable to rapid obsolescence — vendor-backed competition and the current pace of SDK development mean the surface can shift faster than most delivery roadmaps anticipate.
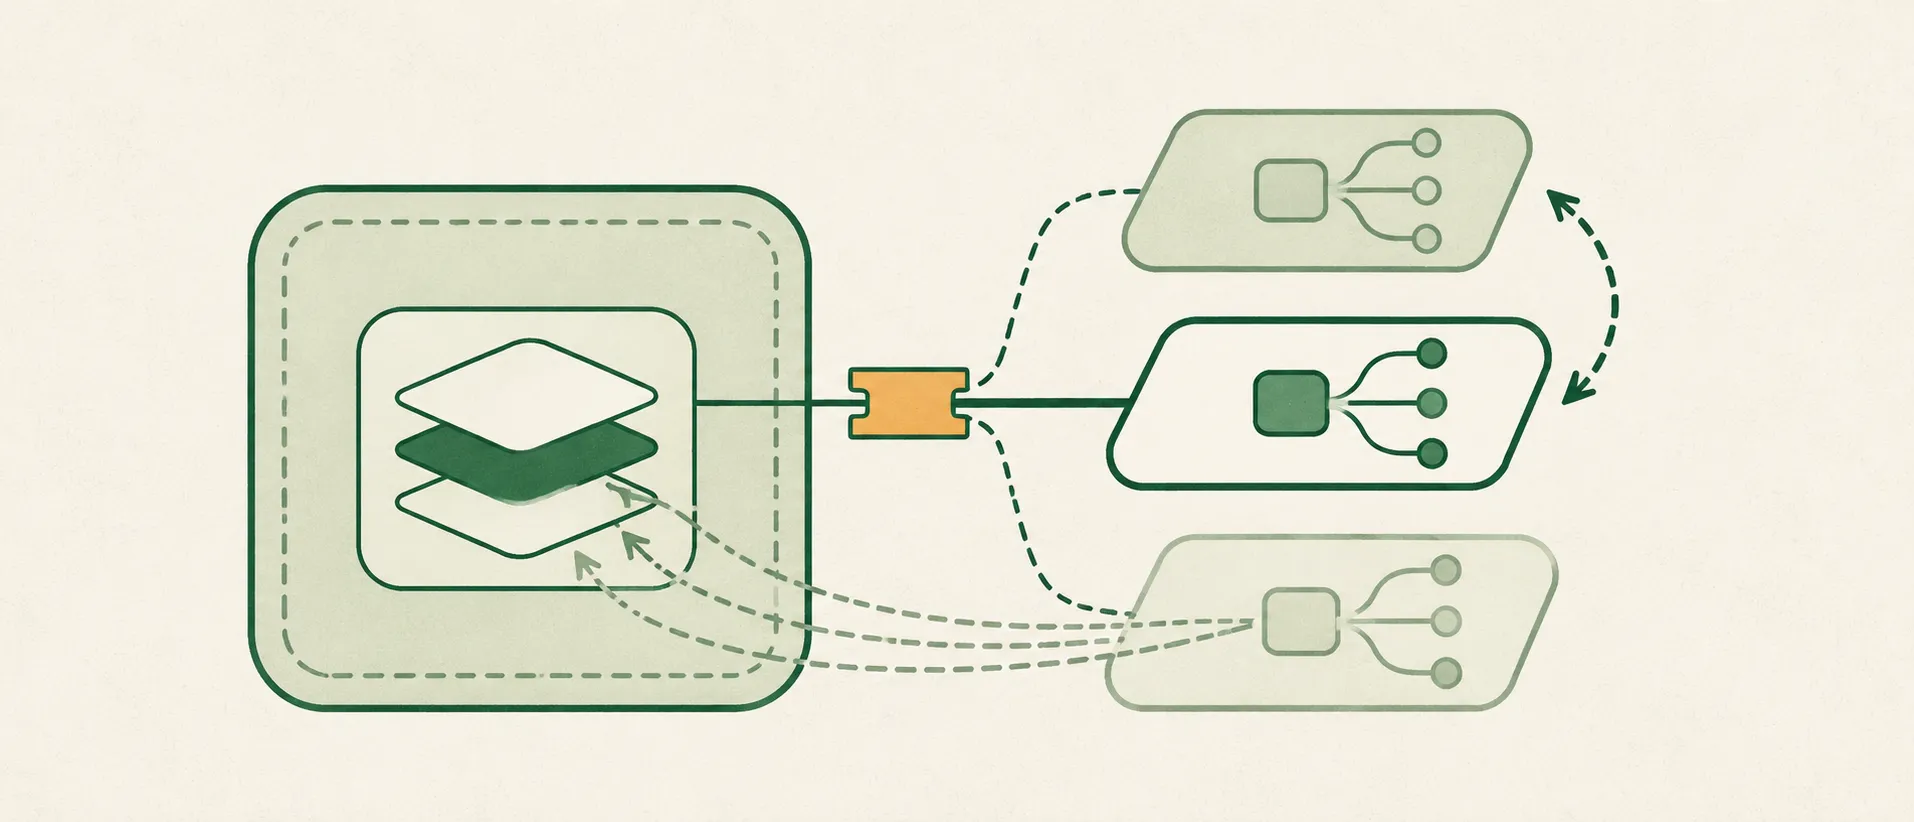
The architectural defense is isolation. Wrap SDK calls behind your own interfaces. Your orchestration logic, your business rules, your evaluation harness — they should depend on your abstractions, not on the framework’s public API. The underlying SDK becomes an implementation detail. Replacing it means swapping the adapter, not rewriting the system.
Treat agent SDKs the way you treat database drivers. You don’t architect your application around a specific driver. You depend on a connection interface, swap drivers when performance or licensing requires it, and keep your query logic independent of the driver’s internals. The evaluation criteria are analogous: does it expose traces, does it support your eval harness, how actively is it maintained, how painful is migration?
The developer who ran pip install on Friday wasn’t wrong to experiment. They were wrong to experiment without a plan for what happens when the experiment ships.