
Agent Adoption Is Stuck At Verification
By wGrow Project Team ·
You built an agent. It works in the demo. You deploy it. Now your senior engineers are spending more time reading its output to catch hallucinations than they would have spent on the original work.
You haven’t built an autonomous system. You’ve built an expensive routing layer with a large language model in the middle.
This is where most production agent projects stall. Not because the model is wrong, and not because the integration is broken. Because the cost of verifying what the agent produces exceeds the cost of doing the work without it.
The Human-in-the-Loop Tax
Generating tokens is cheap. Verifying them is not. A senior engineer reviewing agent output for correctness, compliance, or safety costs orders of magnitude more — measured in salary, attention, and the higher-value work that doesn’t get done while they’re reading.
Demo environments hide this. A demo optimises for capability: show the agent doing something impressive in controlled conditions. Production asks something harder — reliability across a long tail of edge cases, and graceful degradation when the agent is wrong.
If a human must read every output before it touches a live database, a compliance record, or a customer-facing surface, the agent isn’t saving work. It’s generating a new review queue. The real blocker to adoption isn’t model context windows or reasoning capability. It’s the absence of lightweight, programmatic evaluation gates — the kind that let you trust outputs without a human reading each one.
The False-Positive Trap in Generative Compliance Checking
A team that builds a compliance checker for water-treatment documentation might aim to automate compliance reviews of safety certifications, regulatory filings, and technical specs that reference things like limits and thresholds.
If the initial architecture is generative end-to-end — feed in the document, get back a compliance assessment — a prototype can work. In production, the false-positive rate becomes the problem. The model can flag minor phrasing variations as severe compliance failures. A sentence reading “maximum allowable concentration” instead of the spec’s “maximum permitted concentration” can surface as a critical issue. Domain experts have to review every flagged item, and human verification time can end up exceeding the baseline manual review time the system was supposed to replace. The team has then generated work, not saved it.
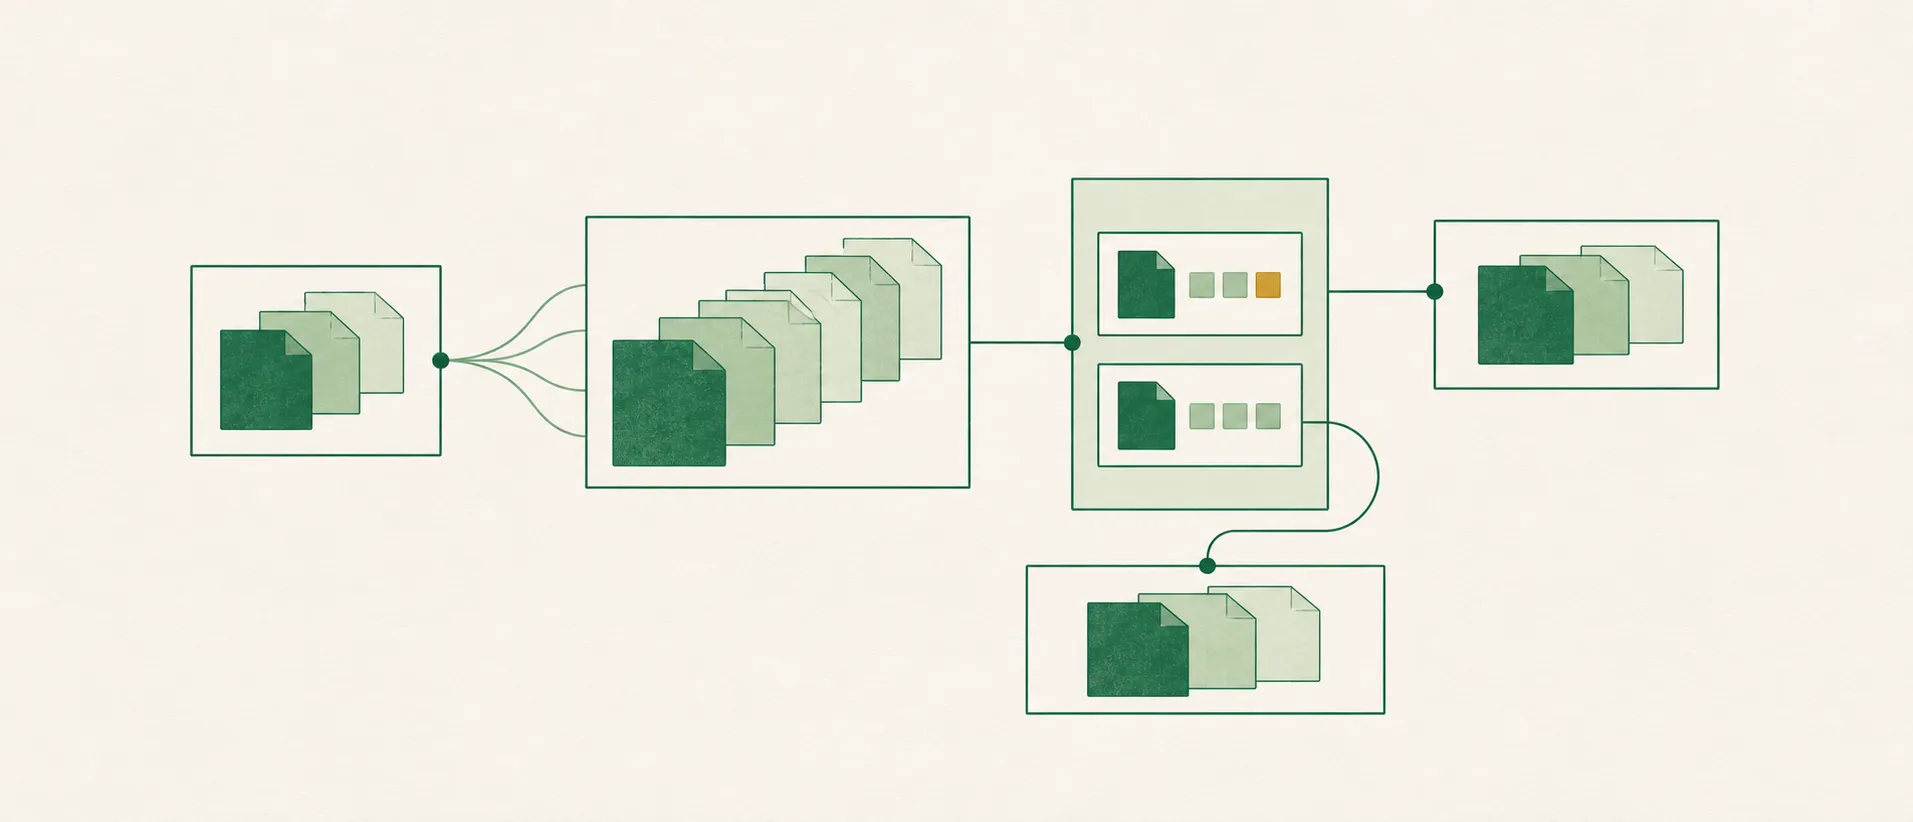
The fix is architectural, not prompt-based. Build deterministic rule engines and place them between the LLM and the human dashboard. The LLM handles one bounded task: raw data extraction from unstructured documents — pulling out values, units, clause references, and measurement types. That’s a scoped task it does reliably.
The actual compliance verification runs on traditional code. Structured rules. Explicit thresholds. If the extracted value exceeds the regulatory ceiling, a flag fires. If it doesn’t, it doesn’t. No probability involved. Humans only see items that survive the rule engine.
With the rule engine upstream, false positives on the verified output path fall — items reaching the human dashboard have already cleared deterministic checks, so reviewers are no longer triaging noise. Review effort shifts from a mounting queue to a short final pass. The system saves work because verification is no longer a human task by default.
Scaffolding Crews and Proprietary APIs
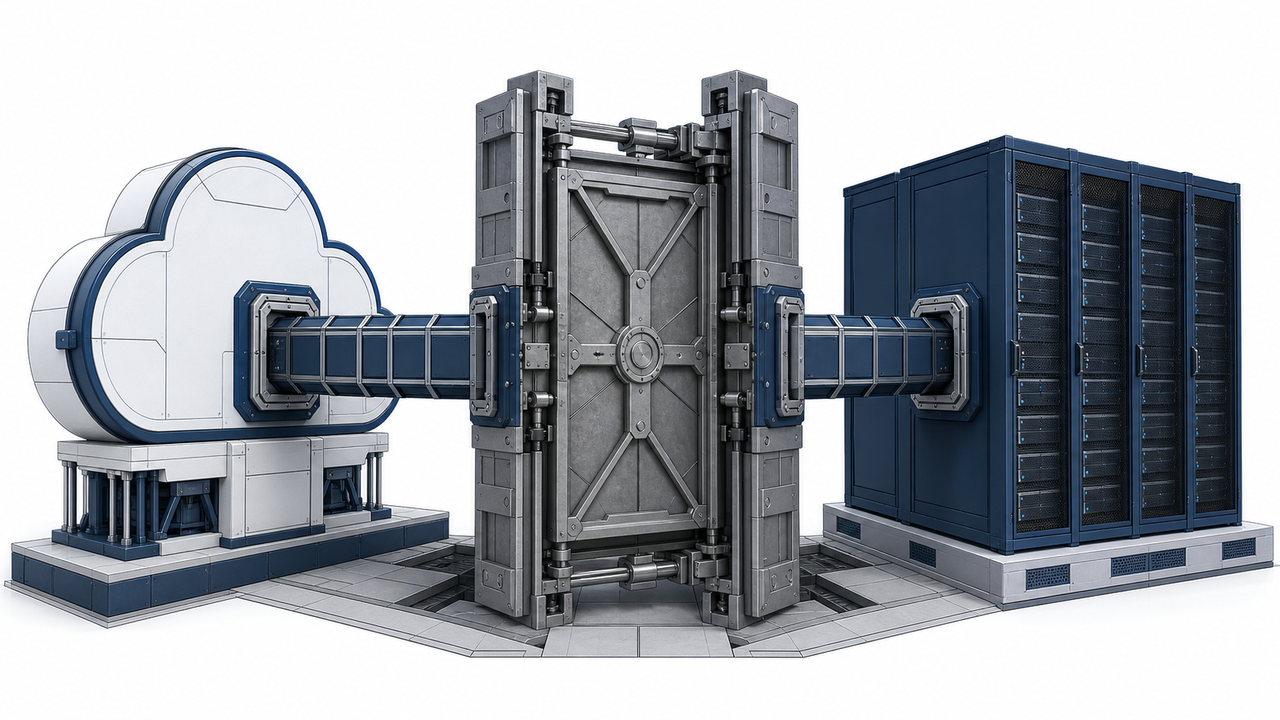
Agent crews can be used for code scaffolding. Generating boilerplate is tractable. Generating code that respects undocumented or proprietary API specifications is something else.
When a project involves hardware interfaces and vendor SDKs with thin documentation and idiosyncratic method signatures, scaffolding agents can produce code that looks correct — syntactically clean, logically plausible, wrong in the specifics. An API call might use the right method name but pass arguments in the wrong order, or omit a required handshake that appeared only in a vendor documentation footnote.
Human reviewers can catch these. If they have to keep catching them, they tire, and review fatigue sets in. Reviewers start approving outputs too quickly — which is the failure mode that actually matters. A fatigued reviewer is worse than no reviewer, because you have the appearance of oversight without the reality.
Prompt tuning doesn’t solve this. The problem is that the verification step is human and therefore unsustainable at volume.
Build dedicated test fixtures for the agents instead. Each fixture runs against a local stub of the vendor API that enforces the exact method signatures and call ordering required by the SDK. The agent submits code directly to the fixture, which compiles it and runs unit tests against the stub. If the tests fail, the agent receives the failure output and iterates. This loop runs without human involvement.
A human reviews code only after it executes cleanly against the fixture. Review time can shift from a mounting manual queue to a short final pass per component. More importantly, reviewer confidence can rise — the deterministic gate has already handled the mechanical checking. The human is now doing what humans are genuinely better at: architectural judgment and edge-case reasoning.
Moving to Deterministic Eval Gates
The pattern from both scenarios points to the same structural shift. Stop relying on the LLM to self-verify. Build programmatic gates that check outputs before they reach humans or downstream systems.
Don’t use LLM-as-judge for critical production workloads. An LLM evaluating another LLM’s output inherits the same probabilistic failure modes. For compliance checking, schema validation, and code correctness, an extra generative step isn’t a safety layer — it’s another source of variance. Verification for these tasks has to be deterministic.
Validate schema before any agent output reaches a production database. Pydantic, JSON Schema, Zod — the specific library matters less than the practice. Every agent output that touches persistent state must be validated against a schema that rejects malformed or out-of-range values before the write happens. This catches a significant fraction of hallucinations cheaply, at the boundary.
Sandbox all generated code, scripts, or configuration before it touches production infrastructure. The scaffolding test fixture is an instance of this — generated code runs against a vendor API stub before any human reviews it. The compliance rule engine is the adjacent pattern: deterministic verification over extracted fields before results reach the dashboard. The sandbox isn’t optional overhead. It’s the mechanism that makes the agent’s output trustworthy.
There’s one strict heuristic worth applying across the board: if you can’t write a programmatic test to verify an output, don’t let an agent generate it autonomously. In practice, this is clarifying rather than restrictive. It forces you to identify precisely where the agent adds value — tasks where correctness can be defined formally — and where it doesn’t.
The tasks that survive this filter are substantial: data extraction from unstructured documents, code generation within a constrained API surface, classification against a fixed taxonomy, report generation from structured inputs. Real workloads that justify investment in test infrastructure.
The tasks that don’t survive are ones where no programmatic definition of correct exists — strategic recommendations, novel architectural decisions, anything where “correct” depends on context that lives only in someone’s head. Keep humans on those. An agent that routes around a judgment call you can’t formalise isn’t autonomous; it’s unmonitored.
The Test Engineering Mandate
Engineering teams need to stop treating agent evaluation as a post-launch analytics exercise. Build the verification fixtures before you write the first prompt.
The common sequence: build the agent, deploy it, observe failures, retrofit evaluation. That sequence is what produces the review fatigue problem — the evaluation burden lands on humans because nothing programmatic exists to absorb it.
The better sequence: define the output schema, define the programmatic success criteria, build the test fixtures, then build the agent to satisfy them. The fixtures define what “working” means before the agent exists. The agent’s job is to pass them, not to impress a reviewer.
This reframes the economics sharply. Test fixture engineering carries upfront cost, but it’s a capital investment that pays per output. Human review is an operating cost that scales linearly with volume. At low volume, human review can look cheaper. At production volume, it collapses the business case.
Production-grade agent crews should expect to spend the bulk of their engineering effort on test infrastructure, not prompt tuning. That balance can surprise teams who came to agents through prompt experimentation. But prompt tuning only improves the generative step. Test engineering is what makes the output trustworthy enough to run without a human reading it.
Capability without verification infrastructure is shelfware. An agent that impresses in demos but requires continuous human review is a demo system — not a criticism of the model, but a systems design observation. The model is doing what it does. The architecture hasn’t given it the scaffolding it needs to be trusted.
Treat fixture coverage as a prerequisite for agent autonomy, the same way you treat test coverage as a prerequisite for production deployment. An agent with strong fixture coverage, deterministic schema validation, and sandboxed execution downstream can be a genuine production system. One without is a liability dressed as a feature.
The verification problem is solvable. It just requires treating evaluation as engineering, not as an afterthought.