Agent-to-Agent Handoffs Need Zod Contracts, Not Text
By wGrow Project Team ·
The Demo Illusion
A research agent finished its job and tacked one more line onto its output: “Happy to help with further edits.” Our internal RFP pipeline passed that payload, unchanged, to the drafting agent. The drafting agent ignored the technical requirements and wrote a short, warm note about collaborating on edits.
Nothing crashed. No exception fired. The pipeline reported success and handed a human a document about the wrong thing.
That is how natural-language handoffs fail. In a framework tutorial, conversational delegation looks like magic: one agent says “please draft the response based on my findings,” the next one does it, and everyone claps. In production, it’s a liability.
Agents rarely need to chat. They don’t need pleasantries. And “asking for clarification” from a peer that will answer with a guess adds noise, not information. If a handoff depends on the receiver inferring what the sender meant, it will eventually fail, and every extra hop makes it worse.
Cascading Intent Drift
We call this cascading intent drift. The mechanics are simple.
Most agent frameworks default to passing strings between sub-agents. Agent A produces free text, and that text becomes part of Agent B’s prompt. B treats it as instructions, context, or both, and has to decide which. Its output goes to Agent C, which makes the same guess again.
Every step feeds a non-deterministic output into another non-deterministic process. The receiver isn’t parsing a contract. It’s parsing a vibe. That costs tokens, since the receiver burns context window working out what the sender wanted. It also leaves you with at least two plausible readings and nothing to arbitrate between them.
Here’s an illustration, not a measurement. Suppose each handoff preserves the original intent with probability . After handoffs, fidelity is . At per hop, a pipeline that looks fine at one hop keeps only about 77 percent fidelity at five. Real systems will differ, and hops aren’t truly independent. But the shape holds: errors compound. They don’t average out.
A small deviation in step one, like a stray sign-off, can become a different task by step three. In our RFP case, it took a single hop.
Applying Microservice Discipline to Agent Crews
Software engineering solved this problem a long time ago. Services don’t talk to each other in prose. They call APIs with defined request shapes, and a malformed request gets rejected at the boundary. Nobody ships a payments service that accepts “uh, charge the usual amount, thanks!”
Multi-agent systems are non-deterministic microservices. They need the same constraints, and arguably stricter ones, because the failure is quiet. A typo in a microservice call usually produces a 400. A typo in an agent handoff produces a confident, fluent, wrong answer.
So we put deterministic guardrails around the chatty frameworks:
- Every handoff has a schema.
- The schema is defined in code, not in a prompt.
- The sender’s output is validated against it before the receiver sees anything.
- The receiver gets typed fields, not a transcript.
In LangGraph, this means you stop passing a generic messages array between distinct functional nodes. A messages list is fine for a chat UI. Between a research node and a drafting node, it’s a poor interface, because it carries everything, stray pleasantries included. Define a strict state object instead, where each node reads specific fields and writes specific fields.
In TypeScript, the RFP handoff should have looked like this:
import { z } from "zod";

const ResearchHandoff = z.object({
  rfpId: z.string().min(1),
  requirements: z.array(
    z.object({
      id: z.string(),
      text: z.string().min(1),
      mandatory: z.boolean(),
    })
  ).min(1),
  sources: z.array(z.string().url()),
  draftTask: z.literal("technical_response"),
}).strict();
The .strict() call is the important part. It rejects unknown keys, so there’s no field where “Happy to help with further edits” can live. If the research agent tries to smuggle in prose, validation fails and the run stops. The drafting agent never sees it.
Still, a schema doesn’t guarantee meaning. A pleasantry could land inside a free-text field like text, which is why min(1) and typed fields are a floor, not a ceiling. Constrain free text wherever you can (enums, literals, length caps) and treat whatever remains as untrusted.
Fixing the Logistics SME Routing Pipeline
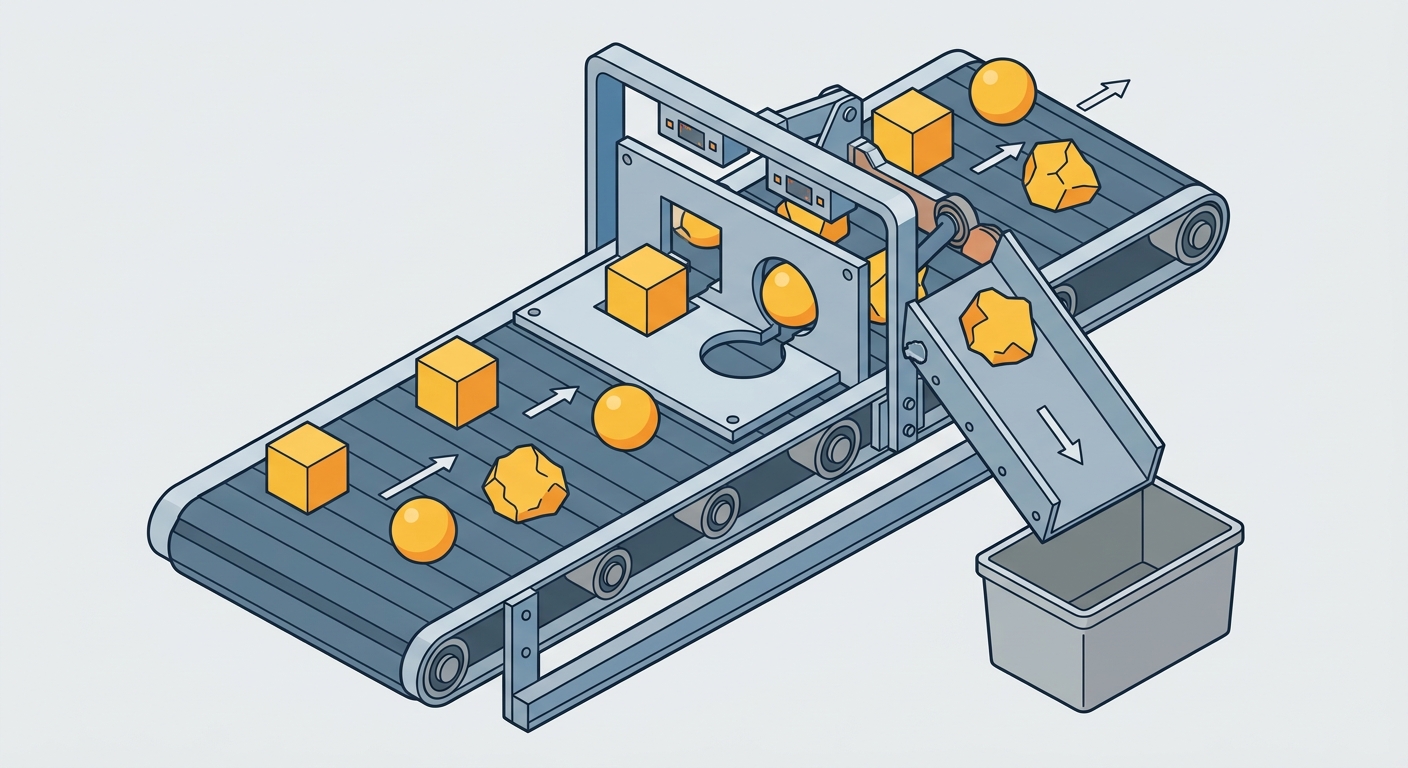
Routing outcome change. Before: 12% measured misroutes. After: invalid outputs surfaced as validation rejections instead of silent misroutes. We did not publish a clean, comparable error rate for the second state, so there is no “after” number to chart.
We hit the same problem from a different direction on a LangGraph deployment for a logistics SME.
The first iteration used conversational routing. A supervisor agent read the incoming request, decided which specialist should handle it, and told that specialist in plain language what to do. It worked in testing. In production, our measured routing error rate was 12 percent. That figure comes from our own review of that deployment’s routed tasks, not from a benchmark.
The errors weren’t exotic. Sometimes the supervisor named a destination that didn’t exist. Other times it described the task in a way that a different specialist read as its own. Free text gave the model room to invent, and it used that room.
So we removed the conversational handoff. The routing agent now outputs a Pydantic model with a strictly typed Enum for the destination node:
from enum import Enum
from pydantic import BaseModel, ConfigDict

class Destination(str, Enum):
    QUOTE = "quote_node"
    TRACKING = "tracking_node"
    CUSTOMS = "customs_node"
    ESCALATE = "human_escalation"

class RoutingDecision(BaseModel):
    model_config = ConfigDict(extra="forbid")

    destination: Destination
    shipment_ref: str
    task: str
Note the extra="forbid" line. Pydantic ignores unknown fields by default, so without it the model would silently drop them instead of rejecting them.
The graph’s conditional edge reads destination and nothing else. If the model returns anything outside the Enum, validation fails.
Silent misroutes stopped being the main failure mode. An invalid destination now fails validation at the boundary, which surfaces immediately and loudly, and we retry it or escalate it to a person. We never published a clean second misroute rate, so read this as a change in how the system fails, not as a comparable before/after metric. One caveat: an Enum can’t tell you whether the model picked the right valid destination. It only guarantees the choice is a real one.
The fix was structural. We didn’t write a better prompt or add a “please be careful” line. We took away the LLM’s ability to invent a routing destination. The ESCALATE member is deliberate. When the model has no good answer, it needs a legal way to say so. Otherwise it will make one up.
Validated JSON or Execution Halts
| 1 | from pydantic import BaseModel | |
| 2 | from typing import Literal | |
| 3 | ||
| 4 | class RoutingPayload(BaseModel): | |
| 5 | destination: Literal['assign_driver', 'escalate_human'] | ← ① |
| 6 | extracted_entities: dict | ← ② |
| 7 |
- ① LLM must pick an exact string. No chat allowed.
- ② Downstream receiver expects guaranteed keys.
The rule we now apply is short: treat LLM orchestration like backend microservices.
In practice:
- Pick a schema library and use it everywhere. Zod in TypeScript, Pydantic in Python. Both are cheap to adopt, and both give you a boundary that either passes or fails.
- Validate every handoff. Not most of them. Every one. The hop you skip because “it’s just internal” is the one that will carry the stray pleasantry.
- Reject unknown fields. Free-text escape hatches defeat the point. If you need a human-readable note, give it a named, length-capped field, and tell downstream agents to ignore it for control flow.
- Halt on failure. A payload that fails validation does not move downstream. Don’t let a receiving agent try to interpret corrupted state. It will try, it will sound confident, and you’ll hear about it from a customer.
- Retry at the source. Send the validation error back to the producing agent, allow a bounded number of retries, then escalate to a human.
There’s a fair objection here: strict schemas make the system less flexible. True, and that’s the point. Flexibility at the handoff is where drift comes from. But the cost is real. Schemas need maintenance, and every change to a handoff means a change in code. For a two-step prototype nobody depends on, that overhead may not be worth it. Once a pipeline has several hops or real users, it usually is.
Let the model be creative inside a node. Between nodes, it should be boring.
Natural language still belongs at the edges. Users talk to agents in prose, and agents write prose back to users. Between agents, prose is a liability with a friendly tone.
Agent frameworks may well ship typed handoffs as the default, the way web frameworks ship request validation. Until they do, add it yourself. Agents don’t need to collaborate over chat. They can execute against validated JSON contracts.